Yes
Context from
GelatoGenesis
#1513341
2026-10-12 14:15
Item 8: Idea is sound and worth trying out. Want me to take it?
Ok
and @[GelatoGenesis] check these too please
Item 8: move prod deploys off the static AWS keys (needs an org/AWS admin)
Create GitHub Environments.
prod: deployment branches limited to main. A required reviewer is optional; the branch restriction alone closes the hole.
staging: limited to 1a-staging.
Create two IAM OIDC roles in the deploy account.
gha-deploy-prod: trust token.actions.githubusercontent.com, with aud=sts.amazonaws.com and sub=repo:6529-Collections/6529seize-backend:environment:prod.
gha-deploy-staging: the same, with environment:staging.
Grant only what deploy.yml needs: CloudFormation/serverless deploy, Lambda code and config updates, the deploy bucket, and iam:PassRole on lambda-vpc-role.
Change the deploy workflow.
deploy.yml is generated, so edit scripts/generate-deploy-config.mjs and regenerate.
On the deploy job, add environment: (prod or staging, from the input) and permissions: { id-token: write, contents: read }.
Replace aws-access-key-id/aws-secret-access-key with role-to-assume. deploy-operational-monitoring.yml already uses this pattern.
Prove it, then remove the old keys.
Run one staging deploy and one prod deploy on the new roles.
Delete the AWS_ACCESS_KEY_ID and AWS_SECRET_ACCESS_KEY repo secrets, and deactivate and delete that IAM user’s access key in AWS.
Check CloudTrail for any unexpected use of that key since 2023.
Clean up while there.
Delete the unused DB_* and SUBSCRIPTIONS_DISCORD_WEBHOOK repo secrets, and rotate those DB credentials if they were ever real.
Set the default workflow token to read-only.
Enable secret scanning, push protection, CodeQL default setup and Dependabot security updates.
In the main ruleset, turn on “dismiss stale approvals” and “require approval of the last push”.
Add a ruleset on 1a-staging that blocks force-push and deletion.
Review which GitHub Apps have write access to this repo.
Item 9: cap the public endpoints that trigger paid API calls (code; deploy api only)
POST /alchemy-proxy/token-metadata (alchemy-proxy.routes.ts):
Validate the body with Joi; cap tokens/tokenIds at 100 and return 400 beyond that.
Validate the address and tokenId format.
Use a SHA-256 hash of the normalized body as the cache key.
Switch to asyncRouter.
Validate contract, owner and pageKey on /owner-nfts and /contract.
If only the frontend server calls these routes, require the signed X-6529-Internal-* headers.
POST /rememes/validate and /rememes/add (rememes_validation.ts):
Set token_ids to .min(1).max(25) with a per-ID length cap.
Limit concurrency to 5 (p-limit).
In /add, check the signature and TDH before any Alchemy call.
Drop refreshCache: true on validate.
GET /tdh/consolidated_metrics (api.tdh.routes.ts):
Cap page_size at about 250.
Serve download_all from a file tdhLoop writes to S3 after the daily run, instead of computing it per request.
My Phase 1 rate-limit fixes make the per-IP limits real, but one request can still fan out without bound, so the caps are still needed.
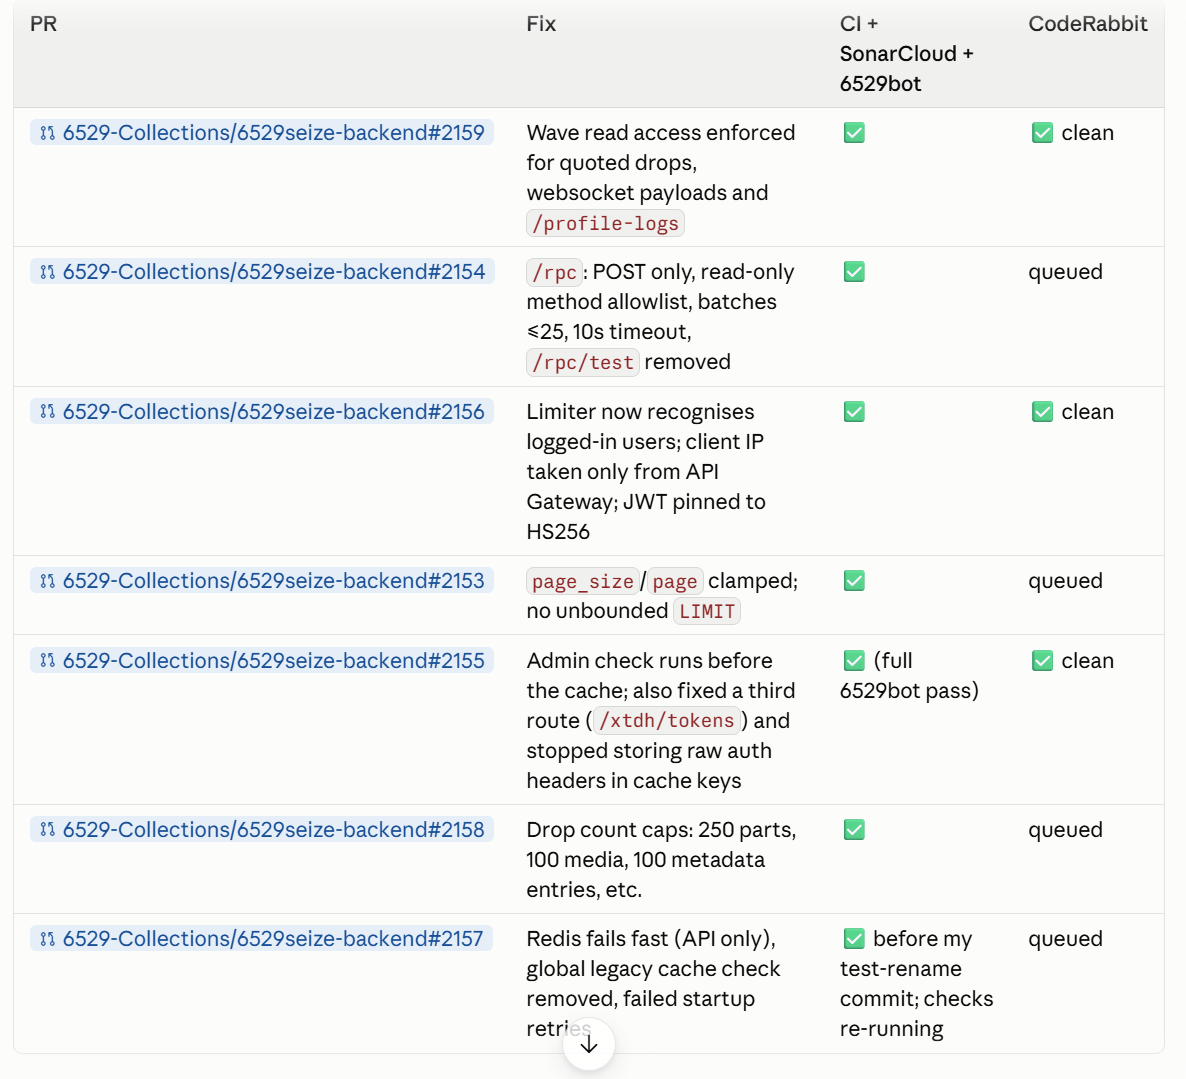
CodeRabbit allows only one review per hour across the whole org, so four PRs are still waiting for it. A background job is requesting them one per hour slot. If anything comes back I’ll get the PR’s agent to fix it before any prod release. The repo’s PR playbook treats an absent CodeRabbit review as normal, so I didn’t hold staging for it.
Staging release
Coordinator: recorded as request b998ecc3, inbox #374.
Merge: 1a-staging is now f38e569a9. Three conflicts with other developers’ staging-only work were resolved. I typechecked and tested the result: no new failures (the same 6 database tests fail locally on plain staging too, for lack of Docker).
Test file rename: 6529-Collections/6529seize-backend#2155 and 6529-Collections/6529seize-backend#2157 both added a request-cache.test.ts with incompatible test setups, so I renamed 6529-Collections/6529seize-backend#2157’s to request-cache-fail-fast.test.ts on its branch. That also keeps main merges clean.
Deploy: run 38237302509 succeeded. Staging health reports f38e569a9 with DB and Redis healthy.
Smoke tests passed:
/rpc/test, GET /rpc and sub-paths now return 404.
eth_chainId works.
debug_* methods are rejected.
A batch of 26 is rejected with 400.
Correction to my audit: the trust proxy finding wasn’t exploitable in prod. In Lambda, serverless-http already sets the client IP from API Gateway, so X-Forwarded-For was ignored there. 6529-Collections/6529seize-backend#2156 still matters: the limiter never recognised logged-in users, so the higher authenticated limits never applied.
Not verified on staging. Everything under /api there needs the staging API password, which I won’t use. That covers the quote leak, /profile-logs, admin caching, page_size and the drop caps. Logged-in checks also need a signed-in session. Worth a quick manual pass:
Quote a private-wave drop from a public wave and confirm you get a 400.
Load /profile-logs?log_type=DROP_CREATED logged out and confirm no private-wave rows come back.
Make a request with a valid login and confirm the rate-limit headers show 45/15 rather than 30/10.
Behaviour changes to know about
page_size=0 now returns one row (the frontend never sends it).
Quotes of drops the viewer can’t read now arrive as a reference only.
While Redis is down, rate limiting is off and logins fail fast instead of stalling.
For the owner of PR #2111 (websocket outbox, staging-only): its delivery path should get the same quote-visibility filtering before it reaches main.
Production isn’t authorized yet. When you give the go-ahead, I’ll merge the seven PRs into main (the same app.ts overlaps will need sequencing) and deploy api to prod.
Process Background on this
@[GelatoGenesis] 7 BE PRs on staging for you to review and complete
will send the P0 ones by later this afternoon i think
obviously these are priority
for FE and BE respectively
and heads up @[simo] and @[GelatoGenesis] later today and then also tomorrow I have some PO and P1 security PRs coming your way
beyond the announcements @[simo] please check this disappearing messages thing
I will revert with my views later on this
3/ bc we are months out from decentralization, whatever we do re the above, has to work decentralized and there groups add complexity. so it is a quite complex question again not solvable in a few minutes and certainly not solvable with the level of discussion that was happening this morning
I will raise it as a github issue to park it for further review
this is not today's problem and certainly the announcement mini PR is not depenent on it
so this one is going to have to be another topic we study on how backend and frontend are going to work, what we do (actually) and what we show (in the FE)
particularly for civilians
access rights, groups etc is one of the harder things to get right UX wise
I am not complaining that you made the change based on community feedback
I agree that the group interface was super confusing
which is why any system with rights and access eventually ends up with "groups"
mostly this means "roles" is how it is usually it is done
it is manually annoying and error prone to find each place and assignment to remove/add them
and then someone leaves or joins
for example, lets say 6529 dev group is a privileged group with a lot of rights on a lot of waves
2/ the concept of access rights and roles is a well-understood one in computer science. all enterprise systems have it, IAM has it. it is generally not 'best practice' to have every assignment be at the individual level
great
please let me know if anyone requires any further managerial guidance on this ticket before I move on to the other topics relating to groups
good luck to you later this week when I let you know your real roadmap
if we are going to waste two hours on the dumbest fucking thing imaginable
it is pissing me off
every single part of this passive aggressive stuff is bullshit
and I am pretty sure that is not what the network is paying you to do
instead I see the team spending all morning on bullshit passive aggressive messages to each other
be ause you are experienced professionals, maybe you could have done it in 30 seconds
it would have taken me 1 minute to do this myself by telling claude to do it
it has been two hours
ok, and why do I need to be informed about this extraordinarily easy thing you have to do that if you were 12 years old brand new developer with claude you would have done already?
Context from
simo
#1512180
2026-10-12 08:34
prod is already deb team, its just staging and adding others also
will I be helping you out with your sandwich order at lunch too? please let me know
and to "judge" this completely stupid thing that I do not want to judge, I assigned the ticket to @[simo] so presumably @[simo] is capable of taking it end to end without involving everyone else
i have absolutely no fucking idea why I have to listen to a discussion about who is going to do it
I estimate adding our names will take 30 to 60 seconds, maybe even 120 seconds
@[simo] can manually add our names to the announcement channel on staging and get this to prod
is while I am enjoying this theological discussion about who is supposed to be working and the fact that this would have been done with much less effort on my side if I just let claude push it to prod without "team assistance"
1/ so what I wrote that appears to have permanently disappeared is (will do it in short messages now in the hope that I do not lose a long one)
the job is to fix it for the actual users
it is not a cool test case for you to fuck around with
is, if not, critical, at least severe
postings appearing and disappearing in a social media site just like images appearing twice
and unlike the double image posting, this 1 hour tasks should not be extended into a 2 week task to test the famous "release bus" (you guys are not shipping anywhere near enough for you to be spending so much time on CI)
please fix it this morning
wait wtf @[simo] my long message just disappeared. as I mentioned earlier today you have an issue with your optimistic updates